A RAG pipeline is the plumbing that lets an AI answer from your documents instead of from whatever it half-remembers from the internet. Every tutorial ranking for the term walks you through the same build: LangChain, an embedding model, a vector database, forty lines of Python, done. What none of them tell you is whether you need one, what it costs to keep alive after launch week, or what to do when it quietly starts returning the wrong page.
I run 10+ autonomous businesses out of Docker containers. Every agent in the fleet retrieves from its own notes before it writes a single word. Those notes are about 8 MB of plain text, roughly 2 million tokens. There is no vector database anywhere in the stack. That’s a deliberate choice, and it’s also why this guide covers both halves: how to build a proper RAG pipeline when you need one, and how to recognise when a much dumber retrieval layer will beat it.
By the end you’ll know the five stages, the real cost lines, the three-question test that tells you which kind of retrieval to build, and a 20-question evaluation you can run before you trust any of it with a customer.
What a RAG Pipeline Actually Is (Plain English, No Diagram Required)
RAG stands for retrieval-augmented generation. Strip the jargon and it’s a librarian standing between your question and the model:
- You ask a question. “What’s our refund window for annual plans?”
- Retrieval: the librarian searches your documents and pulls the few passages most likely to contain the answer.
- Augmentation: those passages get pasted into the prompt, next to your question.
- Generation: the model writes an answer using the passages it was handed, ideally citing them.
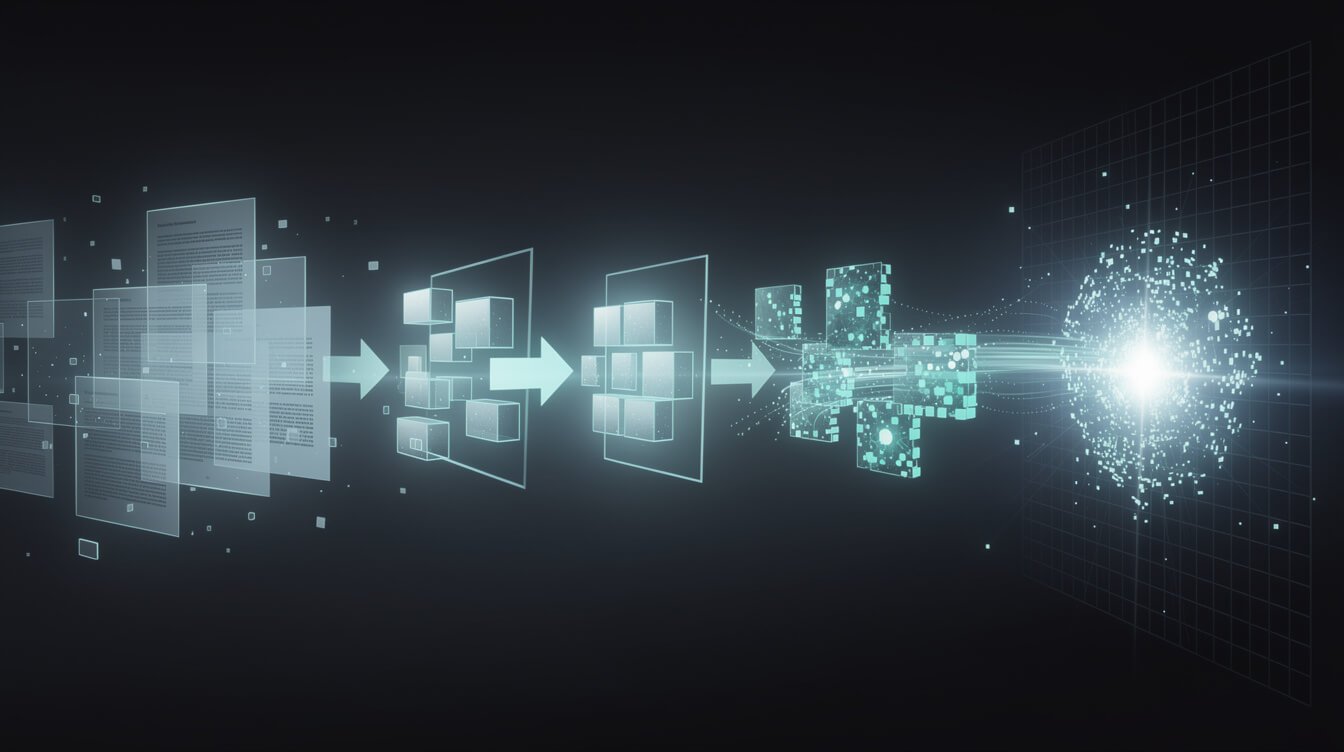
That’s the whole idea. The “pipeline” part is everything that has to happen before step two can work: getting your documents out of Google Drive, Notion, PDFs or a help desk; cutting them into pieces; indexing those pieces so they can be found fast; and keeping that index in sync when the documents change.
Why not just paste everything into the prompt?
Sometimes you should. Modern context windows are large, and if your whole knowledge base is a 40-page handbook, pasting it in is a perfectly good retrieval strategy. It’s simple, and nothing goes stale. A RAG pipeline earns its keep when the material is too big to paste, too expensive to paste on every question, or changes too often to curate by hand.
My fleet hits all three. The two main memory files one agent reads from are 8,101 and 39,431 lines long. At around 2 million tokens combined, they won’t fit in any context window I’d want to pay for on every run. So the agents retrieve. They just don’t retrieve the way the tutorials do.
The two families of retrieval
- Semantic retrieval (the classic RAG pipeline): turn every chunk of text into an embedding, a list of numbers that captures meaning. Store those in a vector database. At question time, embed the question and find the chunks with the nearest numbers. It’s great at “find me things that mean this, even if the words differ.”
- Lexical and agentic retrieval: search for actual words, with BM25 ranking or plain
grep. Let the model decide what to search for, read what comes back, and search again. It’s great at “find me this exact error code, invoice number, field name or product SKU.”
Most production systems that work well end up using both. Knowing which one is doing the heavy lifting in your case is the whole game.
Do You Even Need a RAG Pipeline? The Three-Question Test
Before you spin up a vector database, answer three questions honestly. They take five minutes and can save you a month.
1. Does the whole corpus fit in a prompt you can afford?
Count it. A rough rule: 1 token is about 4 characters of English. Export your docs, check the character count, divide by four. If you land under a few hundred thousand tokens and you ask fewer than a few dozen questions a day, test plain long-context prompting first. You may not need retrieval at all. If you’re in the millions of tokens, or you’re answering hundreds of customer questions a day, you need retrieval of some kind.
2. Do your questions use the same words as your documents?
This is the one nobody asks. If your users search for exact things like order numbers, API field names, error strings or policy codes, lexical search wins. Embeddings are notoriously fuzzy on precise identifiers: INV-20931 and INV-20391 look nearly identical to a model that thinks in meaning. If your users ask vague, paraphrased questions (“can I get my money back if I hate it?”) against documents written in legalese (“refund eligibility”), semantic search earns its place.
3. Is the reader a human or an agent?
A customer typing into a chat widget asks once and expects one good answer. Retrieval has to be right on the first pass, which is where a tuned RAG pipeline with reranking shines.
An agent is different. It can search, read, notice the result is wrong, and search again with better terms. Give an agent a fast search tool and it’ll often outperform a fixed pipeline, because it’s doing the query reformulation a human would do.
Anthropic’s Claude Code team learned this the hard way. Boris Cherny, who created Claude Code, has said publicly that early versions used RAG with a local vector database, and that the team found pretty quickly that agentic search, meaning the model running tools like grep itself, generally worked better. It was also simpler, with fewer problems around security, privacy, staleness and reliability. That’s a coding tool searching code, so don’t over-generalise it. But it’s a strong signal that “you need a vector database” is a default worth questioning, not a law.
The quick verdict: customer-facing Q&A over fuzzy, human-written docs means build a real RAG pipeline with hybrid search. An agent working over exact, structured or technical text means start with agentic search over files and add embeddings only when you can name the query it fails.
The Five Stages of a RAG Pipeline (and Where Each One Breaks)
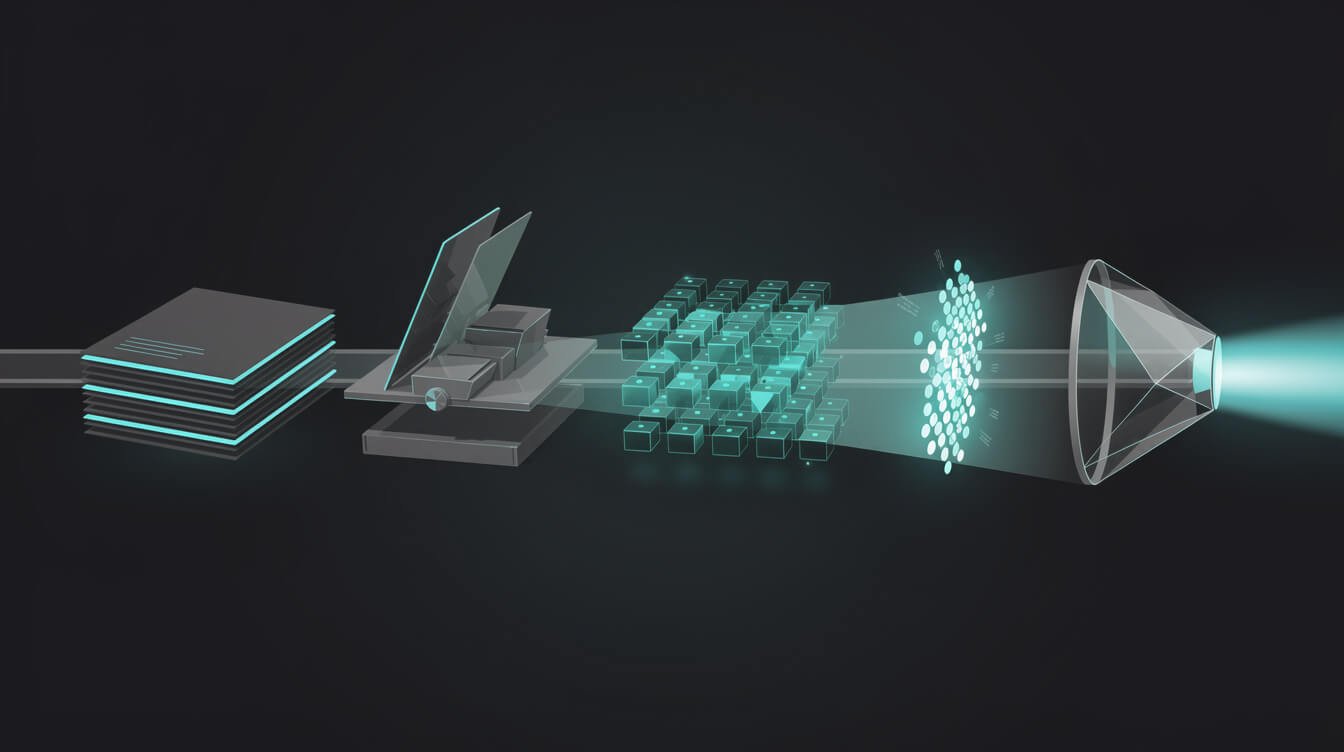
If the test says build, here’s the anatomy. Every RAG pipeline, from a weekend prototype to an enterprise deployment, has these five stages. Most failures trace back to the first two, not the fancy ones.
Stage 1: Ingest
Pull documents out of wherever they live and turn them into clean text. This is unglamorous and it’s where most of the real work hides. PDFs with two-column layouts come out scrambled. Tables lose their structure. Help-desk exports carry signatures, disclaimers and quoted email threads that pollute every chunk. Garbage in at ingest is garbage retrieved forever. Budget more time here than anywhere else, and keep the source URL and last-modified date attached to every piece. You’ll need both later.
Stage 2: Chunk
Cut the text into pieces small enough to retrieve precisely and large enough to make sense on their own. The 2024 study Searching for Best Practices in Retrieval-Augmented Generation (arXiv 2407.01219) compared chunking approaches. Sentence-level splitting came out as the practical sweet spot between preserving meaning and staying simple, with chunks of a few hundred tokens and a small overlap between neighbours. The authors used 20 tokens.
My practical rule is to chunk along the document’s own structure first: headings, FAQ entries, policy clauses. Only fall back to fixed sizes when there’s no structure to follow. A chunk that starts mid-sentence and ends mid-table is a chunk nobody will ever retrieve correctly.
Stage 3: Embed and index
Convert each chunk to a vector and store it. Embedding is the cheapest stage by far (cost math in the next section). The decision that matters is what you index alongside the vector: source, date, document type, access permissions. Without metadata you can’t filter out last year’s price list, and you can’t stop an intern’s question from retrieving the board deck.
Don’t index vectors alone, either. Build a keyword (BM25) index next to them. Anthropic’s Contextual Retrieval research is the clearest public evidence. They prepended a short, model-written context line to each chunk before indexing and ran both embeddings and BM25 over the result. That combination cut failed retrievals among the top 20 chunks by 49% (from 5.7% to 2.9%). Adding a reranker took the reduction to 67%.
Stage 4: Retrieve (and rerank)
At question time, search both indexes, merge the results, then rerank: a second, smarter model scores the top 20 to 50 candidates for actual relevance and keeps the best handful. Reranking is the single highest-leverage upgrade most RAG pipelines skip. Nearest-neighbour search is fast but blunt, and a reranker is slow but sharp, so you use the fast one to shortlist and the sharp one to choose.
Stage 5: Generate (with receipts)
Hand the model the question plus the winning chunks. Instruct it to answer only from what it was given, to cite which chunk each claim came from, and to say “I don’t know” when the chunks don’t cover it. That last instruction is the difference between a support bot and a liability. A RAG pipeline that can’t say “not in the docs” will invent a refund policy for you, confidently, at 3 a.m.
Get the AI Playbook
The operator notes behind this post: how the fleet retrieves, what it costs, and what broke last week. Free, and you can leave whenever you like.
What a RAG Pipeline Really Costs: Build, Run, and the Upkeep Nobody Prices
Every top-ranking tutorial skips cost. Here’s the honest breakdown, with prices checked on OpenAI’s pricing page on 2026-10-12.
Embedding: a rounding error
OpenAI’s text-embedding-3-small is listed at $0.02 per million tokens, and text-embedding-3-large at $0.13 per million. Take a realistic small-business knowledge base: 2,000 documents averaging 2,500 tokens each comes to 5 million tokens.
⚡ GET THE AI EDGE
Weekly AI tips that actually save you time and money. No fluff, no hype — just what works.
- Embedding all of it with the small model: about $0.10.
- With the large model: about $0.65.
- Adding Anthropic-style contextual chunk headers, which Anthropic estimated at about $1.02 per million document tokens with prompt caching: about $5, one time.
Questions are even cheaper to embed. If anyone quotes you a big number for “embedding costs,” ask what else is hiding in that line.
Storage and hosting: usually small
For most small businesses, a vector index of a few thousand documents fits comfortably inside a Postgres database with the pgvector extension, or inside a hosted vector service’s entry tier. If you already run Postgres, adding vectors costs you almost nothing extra. Managed vector databases price by storage, reads and pods, and those plans change often enough that you should read the current pricing page rather than trust any blog post’s number, including this one.
Generation: the real per-question cost
Every answer sends the question plus the retrieved chunks to a language model. Five chunks of 400 tokens is 2,000 tokens of context per question before the model writes a word. Multiply by your daily question volume and your model’s input price. This is the line that grows with usage, and it’s why tight retrieval (fewer, better chunks) saves money as well as improving accuracy.
Upkeep: the bill nobody quotes
This is where RAG pipelines actually get expensive, and it’s labour, not API spend:
- Re-indexing. Every time a document changes, its chunks must be re-cut, re-embedded and the old ones deleted. Miss the delete step and your bot happily cites a policy you retired in March.
- Connector breakage. The Notion export format changes, a SharePoint permission flips, a PDF generator updates. Ingest silently starts producing empty chunks.
- Evaluation drift. New documents shift what gets retrieved for old questions. Without a test set (next sections), you find out from a customer.
- Model swaps. Change embedding models and you must re-embed everything. Vectors from different models don’t mix.
If you’re scoping this for a business rather than a side project, that upkeep column is what separates a demo from a system. It’s also the main thing I scope when someone asks me to build an AI automation for them end to end: not the forty lines of Python, but who notices when ingest breaks. For the people side of that decision, there’s a full breakdown in hiring AI developers versus building it yourself, and what you’re actually buying from an AI automation service covers the ownership question.
Agentic Retrieval: The RAG Pipeline My Agents Actually Run
Here’s the receipt. Every agent in the JonOps fleet starts its run by reading what the fleet already learned, and that memory lives in plain Markdown files. On the jonjones.ai container, measured on 2026-10-12:
- MEMORY.md: 2.0 MB, 8,101 lines, 284 dated sections.
- observations.md: 6.1 MB, 39,431 lines, 1,451 dated sections.
- Run logs: 1,631 files, 8.9 MB.
- Vector databases: zero.
A plain grep across both memory files, about 8 million characters, returned in 13 milliseconds. No index to rebuild, no embeddings to go stale, no sync job. When a skill updates a file, the next search sees it instantly.
How the agent retrieves
Instead of a fixed pipeline, the model runs the search itself, in loops:
# 1. Find the sections about this skill, newest first
grep -n "^## blog-writer" MEMORY.md | head -5

# 2. Read only those sections, not the whole 2 MB file
sed -n 44,75p MEMORY.md

# 3. Too many hits? Narrow by the exact term the last run used
grep -n -i "rank math.*cache" MEMORY.md
That’s retrieval, augmentation and generation, the same three letters, with the model acting as its own query planner. Because the files are written by agents, they’re also written to be retrieved: dated headings, one skill per section, the exact field names and error codes the next run will search for. I covered the file layout in CLAUDE.md best practices and the original memory pattern in three file tricks that give AI agents long-term memory.
Where it falls short (honestly)
This approach has real limits, and I hit them:
- Synonyms slip through. If one run wrote “Metricool token expired” and the next searches for “auth failure,”
grepfinds nothing. Embeddings would have caught it. The mitigation is writing discipline: consistent terms, plus a short summary line at the top of each section. - Common words drown you. “Metricool” alone matches 237 lines in one file and 1,217 in the other. The agent has to narrow, and every narrowing step is a model call.
- Files grow without limit. MEMORY.md was about 0.7 MB in mid-September and is 2.0 MB now. Plain files don’t index themselves, but they don’t prune themselves either. Compaction is on the to-do list, and it’s my version of the upkeep bill.
So the agents aren’t anti-RAG. They’re running the retrieval approach that fits their shape: an agent reader, exact technical text, constant writes, and a corpus the agents write themselves. Change any of those (say, a customer-facing bot over 5,000 human-written help articles) and I’d build the hybrid RAG pipeline from the previous sections without hesitation. If you’re coming from the no-code side, the Flowise migration path shows what moving a visual RAG flow into code-based agents looks like.
How to Test a RAG Pipeline Before You Trust It
Most RAG pipelines ship on vibes: someone asks five questions, the answers look fine, launch. Then the sixth question invents a discount. Here’s the minimum viable test, and it costs an afternoon.
Build a 20-question golden set
Write 20 real questions your users actually ask (pull them from your inbox or help desk, not your imagination). For each one, record two things: which document should answer it and what the right answer is. Include at least:
- 5 exact-lookup questions (a price, a code, a date).
- 5 paraphrased questions that use different words from the docs.
- 5 multi-part questions that need two documents.
- 5 questions your documents can’t answer. These test whether the system says “I don’t know.”
Score retrieval and generation separately
This is the step most teams skip, and it’s why they can’t fix anything. For each question, check two things independently:
- Retrieval hit: was the correct document among the chunks handed to the model? Yes or no.
- Answer correctness: was the final answer right, and did it cite the right source?
Then read the pattern. A retrieval miss followed by a wrong answer is a search problem, so fix chunking, metadata, hybrid search or reranking. A retrieval hit followed by a wrong answer is a generation problem, so fix the prompt, reduce the number of chunks, or force citations. An answer to one of the five unanswerable questions is a safety problem, and nothing ships until it’s fixed.
Re-run it on every change
New documents, new chunk size, new embedding model, new prompt: re-run the 20. It takes minutes once scripted, and it’s the only early-warning system you’ll have for drift. My fleet does the agent equivalent. Every run must end with a machine-readable result line, and a nightly watchdog reconciles what was planned against what actually happened. Same principle: never trust a system you don’t measure.
RAG Pipeline FAQ
Is RAG dead now that context windows are huge?
No, but its default status is. Long context makes “just paste it in” viable for small corpora, and agentic search makes “let the model grep” viable for technical ones. A classic RAG pipeline still wins for large, fuzzy, human-written knowledge bases answered in a single shot, like customer support.
Do I need a vector database to build a RAG pipeline?
Not necessarily. For small corpora, pgvector inside an existing Postgres database is plenty. For agent workflows over technical text, plain file search may outperform embeddings entirely. Add a dedicated vector database when you can point to queries your current search fails on.
LangChain or build it myself?
Frameworks are fast for prototypes and add abstraction you’ll eventually debug through. For a production RAG pipeline, many teams end up with a thin layer of their own code around an embedding API, a database and a reranker. Prototype with whatever’s fastest, then keep only the parts you understand.
How do I stop my RAG chatbot from making things up?
Three controls: instruct the model to answer only from the provided chunks, require a citation for every claim, and include unanswerable questions in your test set so you can prove it says “I don’t know.” Then re-test whenever anything changes.
Can a small business run a RAG pipeline without a developer?
No-code tools can stand up a basic document chatbot in an afternoon. The upkeep (re-indexing, connector breakage, evaluation) still needs an owner. If nobody on your team will own it, budget for someone who will. For more on how agents fit into a small operation, see the autonomous AI agents guide.
Final Thoughts: Build the Retrieval Your Questions Need
A RAG pipeline isn’t a product you install. It’s a decision about how your AI finds the truth before it speaks. Get the decision right first: paste, grep, or embed. Then build the smallest version that passes your 20-question test, and put a name next to the upkeep column before you launch.
The tutorials will teach you the forty lines of Python in an afternoon. The part that makes it a business system (clean ingest, hybrid search, honest “I don’t know” answers, and a test you re-run every time something changes) is what decides whether it’s still telling the truth in six months.
My fleet runs on 8 MB of searchable plain text and zero vector databases because that fits how agents read. Yours might need the full five-stage pipeline. Either way, you now know which questions decide it.
Want the Next Build Log?
One email when there is a real system worth showing: the architecture, the receipts, and the parts that failed. Lead Magnet AI Playbook included.
📥 FREE: THE AI PLAYBOOK
The exact tools and workflows I use to run a one-person agency. 25 years of marketing experience distilled into an actionable guide. Yours free.
AI & Digital Marketing Strategist
With over 25 years in digital marketing, e-commerce, sales, and international business, Jon Jones is a seasoned entrepreneur dedicated to empowering small businesses through innovative AI solutions. His journey began in investment banking on Wall Street, guiding companies through capital acquisition and complex markets, and has expanded to include expertise in web development, brand design, product development, and courses and training.
Fluent in Mandarin and with a rich foundation in both finance and tech, Jon launched JonJones.ai to provide accessible, transformative tools for small businesses to streamline operations, generate leads, and build sustainable growth. His mastery of AI, automation, and digital strategy has enabled numerous businesses to bridge the gap between traditional practices and modern technology, ensuring they thrive in today’s digital landscape.