Every list of CLAUDE.md best practices you will find today was written by someone who sits next to the agent while it works. They open a session, type a prompt, watch the output, correct it, and ship. Their CLAUDE.md is a seatbelt.
Mine is a steering wheel. The file I am going to show you governs a container that wakes on a cron schedule at 00:05, writes and publishes a full article to a live site, updates four systems of record, and goes back to sleep — with nobody watching. There is no one to catch a bad instruction. Whatever the file says is what happens.
That difference changes which advice is true. When you are present, a vague instruction costs you one correction. When you are not, it costs you a week of silently wrong output. So this is not another template. It is a real file, the measurements of what it actually costs, and — the part nobody publishes — the instructions in it that the model simply did not follow, with the logs that prove it.
What a CLAUDE.md File Really Is — and the One Thing Every CLAUDE.md Best Practices List Gets Wrong
A CLAUDE.md is a markdown file that Claude Code reads automatically at the start of a session and holds in context for the whole run. That part every guide agrees on. The disagreement starts one sentence later.
Most guides describe it as documentation — somewhere to explain your project so the model understands it. That framing is wrong in a way that quietly makes your file worse every time you edit it.
CLAUDE.md is not documentation. It is a standing instruction set that is re-read in full on every single run, and billed to you in tokens every time. Documentation is written once for a human who will read the relevant part. A CLAUDE.md is read entirely, by a machine, on every invocation, forever. Those are opposite economics.
Treat it as documentation and you will keep adding background, because adding context feels free. Treat it as a standing instruction set and three rules fall out:
- Every line must change behaviour. If removing a sentence would produce an identical run, that sentence is costing you tokens and buying nothing.
- Every line is read by every lane. My video-rendering configuration is loaded even when the agent is writing a blog post. More on what that costs below — the number surprised me.
- An instruction you cannot verify is a wish. This is the one most CLAUDE.md best practices lists never mention, and it gets its own section below — because I can show you exactly which of my rules the model follows and which it does not.
If you are still deciding whether to run agents unattended at all, I wrote up what actually runs my 10-brand fleet in production — this post assumes you have made that call and now need the file to behave.
A Real CLAUDE.md From a Business That Runs Unattended, Measured
Here is the actual file, measured as it sits on disk right now:
- 485 lines, 29,597 bytes, roughly 7,400 tokens
- 32 top-level sections
- Governs one brand container; nine more like it run on the same host
What an unattended file needs is not what a coding template suggests: identity and mission, brand voice, the publishing target, the data schema, the media pipelines, literal API call patterns, credential locations, and a block of twelve numbered rules. Three structural choices there are worth stealing.
1. Credentials are located, never stored
The file never contains a secret — only the protocol for finding one: check env | grep KEY first, the .env file is not authoritative, the host injects everything via Docker. Five lines that prevent an agent finding a stale file and confidently using dead credentials.
2. Exact API shapes, not API names
Saying “use the Airtable API” produces guessing. The file carries literal working curl invocations instead — real endpoint, real auth header, real payload shape. An agent handed the exact call does not improvise one.
This matters more than it sounds. One table in my Airtable base uses snake_case field names while every other table is Title Case — and Airtable is case-insensitive when you read but case-sensitive when you write. A skill can therefore read perfectly and fail every write, silently, with an error that looks exactly like an empty queue. That asymmetry hid a broken loop for months. No amount of model intelligence recovers a fact like that; it has to be written down.
3. A numbered, non-negotiable rules block
Twelve rules, numbered, under a heading that says Non-Negotiable: publish immediately rather than draft, never publish without a featured image, never invent data, write for today only.
That block is 922 bytes — 3.2% of the file, and the most load-bearing thing in it. It is also not uniformly obeyed, which is where most CLAUDE.md best practices advice stops and the interesting part starts.
The Instructions Claude Ignored — and the Logs That Prove It
Every CLAUDE.md best practices guide is written in the imperative mood with nothing at stake. So I went through my own log directory and graded my file against reality — counts, not impressions. Here is what came back.
Rule 1 is impossible, and has been from the day it was written
Rule 1 reads: “Always read MEMORY.md at the start of every session.” It is the first rule, under the Non-Negotiable heading.
MEMORY.md is currently 1,971,423 bytes — approximately 493,000 tokens. It does not fit in the context window. It has never fit. No agent has ever executed rule 1 as written, and no agent has ever reported failing to, because “read this file” has no success condition attached to it.
It is the most instructive failure in the file because nothing broke and no error was raised. A rule written when the file was small stayed put while the file grew, and quietly became fiction — still looking authoritative at the top of a list labelled non-negotiable.
Rule 6 is possible, and still dropped 7.6% of the time
Rule 6: “Always end skill execution with SKILL_RESULT: [success|skip|fail] | [summary].” Trivially executable — it is one line of text.
I grepped every non-empty log the fleet has produced:
- 1,584 run logs
- 1,464 contain a
SKILL_RESULTline — 92.4% - 120 do not — 7.6%
The worst offenders are not random: one social skill accounts for 19 misses, and the blog-writing skill — the one producing this very article — accounts for 10. A rule can be clear, short, numbered, flagged non-negotiable, and still be skipped roughly one run in thirteen.
Two rules in the same block are at 100%
Now the control. Rule 2 says every post publishes immediately, never draft. Rule 11 says every post must have a featured image. I pulled the last 50 posts from the live site:
- 50 of 50 published — zero drafts, zero scheduled. 100%.
- 50 of 50 carry a featured image — zero missing. 100%.
Four rules. Same file, same heading, same numbered list, same emphatic language. Compliance of 100%, 100%, 92.4%, and 0%. Emphasis explained none of the variance. Something else did.
Get the AI Playbook
The same operator notes that produced this post — real systems, real numbers, no theory. Free, and you can leave whenever you like.
Obeyed vs Silently Dropped: The Test That Separates Them
Line the four rules up and the pattern is unmistakable — and it is the one finding that reorganised how I think about CLAUDE.md best practices entirely.
| Rule | What it demands | Compliance |
|---|---|---|
| 2 — publish, never draft | A field in the API call that creates the post | 100% |
| 11 — featured image required | A field in the API call that creates the post | 100% |
| 6 — print a result line | A separate act, after the work, read by nothing | 92.4% |
| 1 — read a 493k-token file | An action that cannot physically complete | 0% |
Rules 2 and 11 are not obeyed because they are important. They are obeyed because they are preconditions of an action the agent has to take anyway. You cannot create a WordPress post without supplying a status and a featured media ID. The instruction sits directly on the critical path, so skipping it is not available as an option.
Rule 6 is off the path. The work is done, the article is live, and printing a summary changes nothing downstream at the moment it is skipped — so it survives on attention alone, which is exactly what runs out at the end of a long run. Rule 1 is off the map entirely.
That gives you a genuinely predictive test, and it is the most useful CLAUDE.md best practice I know:
For every instruction in your file, ask: is this a precondition of something the agent must do anyway, or is it a separate act of goodwill? If it is goodwill, assume it will be dropped some fraction of the time — and decide now whether that fraction is acceptable.
Run this audit on your own file
It takes about twenty minutes and it is the highest-value thing you can do to a CLAUDE.md that has been growing for a few months.
- Number every instruction. You cannot measure a paragraph. If a rule is not individually addressable, it is not auditable.
- Write the observable for each one. What would you grep, query, or
curlto prove it happened? Rule 11 has one: thefeatured_mediafield on the post. Rule 1 has none — that absence was the bug, visible before any measurement. - Measure the last fifty runs. Logs, API, database — wherever the evidence lives. Counts, not recollection.
- Sort rules into three buckets. On the critical path (safe to leave as prose). Off the path but verifiable (needs enforcement elsewhere — see the routing section). Unverifiable (delete it or make it verifiable; there is no third option).
- Delete anything that scores zero and cannot be fixed. A rule nothing obeys and nothing checks is worse than no rule, because it makes the file look governed when it is not.
My rule 1 is being rewritten from “always read MEMORY.md” to a bounded read of a specific recent slice — an instruction that can actually complete. I covered the general version of that problem in three ways to bound what your agent reads at startup.
CLAUDE.md Best Practices for Agents That Don’t Write Code
Every result on the first page of Google for CLAUDE.md best practices assumes you are building software. Mine does not ship a line of production code. It writes articles, schedules social posts, sends newsletters, answers email, and runs outreach. Four things change, and all four of them matter more than the repo-specific advice you will otherwise be given.
You have no test suite, so you must manufacture a verifier
A coding agent gets a free, honest oracle: run the tests. A content agent has nothing equivalent. “Did the article publish correctly?” has no exit code.
So the file has to specify the verifier explicitly. Mine requires fetching the live URL after publishing and confirming the new headline actually appears in the returned HTML — with a cache-busting parameter, because a CDN will cheerfully serve you the old page and let you mark the run a success. That lesson cost a real incident: an SEO metadata write returned HTTP 200, acknowledged the change, and the live page still showed the old title thirty seconds later. An API acknowledgement is not evidence that anything rendered.
⚡ GET THE AI EDGE
Weekly AI tips that actually save you time and money. No fluff, no hype — just what works.
Idempotency stops being a nicety
Re-running a test suite is free. Re-running a publisher posts the article twice. An unattended content agent will eventually retry — after a timeout, a crash, a scheduler hiccup — so the file must say what “already done” looks like and how to check for it before acting.
This is why rule 10 exists: write content for today only, never batch ahead. It also needs a timezone-aware check. My WordPress runs at UTC while the container is scheduled in Central Indonesia Time, so evening content lands on the previous UTC date — and the naive “is there a post for today?” query returns zero, reading as total failure when everything is fine.
Voice needs its own file, not a paragraph
Four adjectives will not reproduce a voice. My file carries one compressed voice line and then points to dedicated documents — brand voice, brand rules, a separate email persona read before any reply is drafted. The pointer is cheap; the document only loads in the lane that needs it.
“Done” is externally visible, so the definition must be external too
For code, done is a merged commit. Here, done is a live URL plus four systems of record agreeing with each other — stated explicitly, because an agent that defines done as “I finished writing” leaves your tracking silently out of sync for weeks. The same reasoning drives what actually transfers when you replace a VA with AI.
The Context Bill: What Each Section Actually Costs
Here is the measurement I did not expect, and it is the strongest argument for ruthlessness I can give you.
I broke my CLAUDE.md into its 32 sections and sized each one. The largest single section — 12.5% of the entire file — is a table of placeholder definitions left behind by the setup wizard that generated the file. It explains what each template variable was before it was filled in. It is read on every run, by every lane, forever, and it changes nothing.
Add the two sibling leftovers and 18.3% of the file is setup scaffolding. For comparison, the Non-Negotiable rules block — the part that governs all behaviour — is 3.2%. The wizard residue outweighs the rules by nearly six to one.
Then I tagged every section this blog-writing run actually consulted. The video rendering pipeline (9.1%) was not consulted. Nor the social posting architecture, the social mining config, the email reply guidelines, the search-console instrumentation, the B2B profile, the competitor list.
For this run, 47.8% of the file — roughly 3,460 tokens — was dead weight. Not wrong. Just irrelevant to the lane that was executing, and paid for in full anyway.
Two more leaks worth checking in your own file:
- Unrendered template syntax. Mine still contains 12
{{#if}}expressions that never got processed. Because they never rendered, the model reads both branches — including one that names a product CTA and another that says no products are configured and CTAs should be skipped. Directly contradictory instructions, both live in context, with nothing to resolve them. - Unfilled placeholders. Seven
TODOmarkers remain. One is the brand’s image style guidance, so every lane that generates an image reads the literal stringTODO_JON(IMAGE_STYLE)and then re-derives the style from a design document somewhere else. The instruction is present, is read, is paid for, and is unexecutable.
What to actually cut
This is where CLAUDE.md best practices become arithmetic rather than taste. Cut anything the wizard left behind. Cut any section only one lane uses and move it into that lane’s skill file. Cut every unrendered conditional — pick the branch that is true and delete the rest. Resolve or delete every placeholder. And run the removal test on what remains: if I deleted this, would any run come out different? If not, it goes.
CLAUDE.md vs Skills vs Hooks: Which Instruction Belongs Where
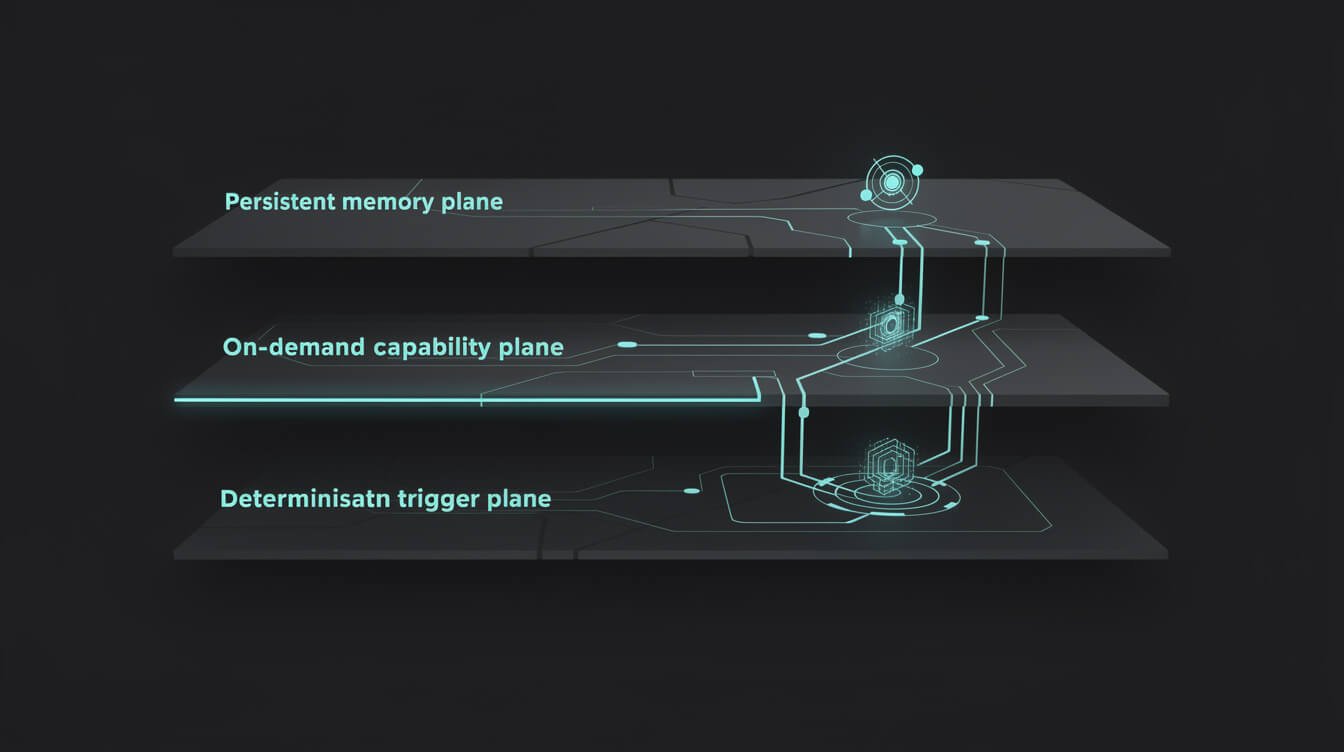
The “Skills versus context bloat” tension is the one genuinely hard trade-off in this topic, and the guides that raise it tend not to resolve it. Having paid the bill, I can give you a routing rule that is concrete rather than philosophical.
The numbers that settle it: my 39 skill files total 468,064 bytes — about 117,000 tokens, 15.8× the size of CLAUDE.md. The single skill executing right now is 47,730 bytes, which is 1.6× the entire CLAUDE.md on its own. If procedure lived in CLAUDE.md, every run of every lane would carry all of it. The architecture is not a stylistic preference; it is the only thing that makes the fleet affordable.
CLAUDE.md — facts true on every run, for every lane
Identity, voice, the target systems, where credentials live, the numbered rules. The test: would a different lane doing completely different work still need this? If only one lane needs it, it does not belong here.
Skills — procedure for one lane, loaded on demand
Step-by-step process, the exact payloads for that job, its specific failure modes. A skill file can be enormous because only the lane that needs it pays — and per-lane corrections belong here, fixed in the skill rather than bolted onto the global file. The same separation logic governs when subagents help and when they add overhead and which plugins earn the context they consume.
Hooks — anything that must happen deterministically
This is the resolution my own measurements forced, and it is the single most actionable conclusion in this post.
Rule 6 runs at 92.4% as a written instruction. It should never have been a written instruction. A deterministic, mechanical, end-of-run action with a defined format is exactly what a hook executes — and a hook does not get distracted at the end of a long run. The same goes for every “always log,” “always notify,” “always clean up” rule in your file.
So the routing rule is:
If it must happen every time without exception, it belongs in a hook. If it is procedure for one lane, it belongs in a skill. CLAUDE.md gets only what is globally true and genuinely needs judgement.
Read that against the audit from earlier and the two halves lock together. The bucket labelled “off the critical path but verifiable” is not a list of rules to write more emphatically. It is a list of hooks you have not built yet. Phrasing was never going to close that gap — my 7.6% miss rate is the proof, and it was sitting in the logs for months.
If you have a half-working CLAUDE.md and no appetite to run this audit yourself, that is the kind of thing I do for people — you can book a working session and we will go through your actual file and logs rather than a template.
Frequently Asked Questions About CLAUDE.md
How long should a CLAUDE.md be?
Short enough that every line changes behaviour. Mine is 485 lines and roughly 7,400 tokens, and I measured 47.8% of it as dead weight for a single run — so “as long as mine” is not the lesson. Length is the wrong metric entirely. The right one is the removal test: delete a section, and if no run comes out different, it should stay deleted.
Where should CLAUDE.md live?
In the project root, where Claude Code picks it up automatically. A personal file at ~/.claude/CLAUDE.md applies across projects — useful for your own working preferences, risky for anything project-specific, because an instruction you forget is global will follow you into unrelated work.
Should I let Claude write its own CLAUDE.md?
For a first draft of structure, yes — /init will scan a project and produce something reasonable. But my largest single section is wizard residue that has been read on every run since, so treat generated output as a starting point you must then cut down. Generation is cheap; the editing is the actual work, and it is the part people skip.
Why does Claude ignore my CLAUDE.md?
Usually it does not ignore the file — it drops specific instructions, and predictably which ones. In my measurements, rules that were preconditions of an action the agent had to take anyway ran at 100%, while a rule requiring a separate act at the end of the run came in at 92.4%, and a rule demanding something physically impossible ran at 0%. Before rewording anything, check whether the instruction is on the critical path. If it is not, phrasing will not save it.
What is the difference between CLAUDE.md and AGENTS.md?
Same purpose — standing instructions read at startup — with AGENTS.md emerging as a vendor-neutral convention and CLAUDE.md being what Claude Code reads natively. The filename is not the interesting decision: every CLAUDE.md best practice in this post about verifiability, critical-path compliance and context cost applies identically to either.
Do I need a CLAUDE.md if I do not write code?
You need it more. A coding agent has a test suite to catch its mistakes; a content or operations agent has nothing equivalent, so the definition of “done” and the method of verification have to be written down or they do not exist. Everything my fleet does is non-code, and the file is what stands in for the missing oracle.
How often should I update it?
Edit on incident, audit on a schedule. Every production surprise should produce either a line in the file or a hook. Separately, re-measure every month or two, because the failure mode here is not a bad edit — it is a good rule going stale while still looking authoritative, exactly like my rule 1 did. Keeping the runtime itself current matters too; I wrote up how to update Claude Code without breaking a running fleet.
Final Thoughts: CLAUDE.md Best Practices That Survive Production
The honest summary: my file is good, it still had one rule at 0% and another at 92.4%, and I knew neither number until I counted. Not neglect — written instructions degrade quietly, and a file full of confident imperatives looks identical whether it is working or not.
Three things to take:
Measure before you rewrite. Every instinct says to fix a misbehaving file by wording it more forcefully. The data says wording was not the variable. Count first.
Put instructions where they can be enforced. Critical-path facts in CLAUDE.md, lane procedure in skills, anything that must happen every time in a hook. A rule that depends on the model remembering at the end of a long run will run at about 92% — fine for some things, not for the ones you believed were non-negotiable.
Delete more than feels comfortable. Nearly half my file was irrelevant to the run executing it, and its biggest section was scaffolding nobody had read since setup. Adding context feels free. It is not — you pay on every run, in every lane, forever.
The real test of these CLAUDE.md best practices is not whether the file reads well. It is whether you can produce the number next to each rule. If you cannot, you do not have a governed agent — you have a hopeful one. And if you want to see what the rest of the stack looks like around a file like this, the full operator’s walkthrough is here, and the server it all runs on is here.
The AI Playbook, Free
Operator notes from a fleet that runs unattended — the measurements, the failures, and the fixes. No fluff, unsubscribe anytime.
📥 FREE: THE AI PLAYBOOK
The exact tools and workflows I use to run a one-person agency. 25 years of marketing experience distilled into an actionable guide. Yours free.
AI & Digital Marketing Strategist
With over 25 years in digital marketing, e-commerce, sales, and international business, Jon Jones is a seasoned entrepreneur dedicated to empowering small businesses through innovative AI solutions. His journey began in investment banking on Wall Street, guiding companies through capital acquisition and complex markets, and has expanded to include expertise in web development, brand design, product development, and courses and training.
Fluent in Mandarin and with a rich foundation in both finance and tech, Jon launched JonJones.ai to provide accessible, transformative tools for small businesses to streamline operations, generate leads, and build sustainable growth. His mastery of AI, automation, and digital strategy has enabled numerous businesses to bridge the gap between traditional practices and modern technology, ensuring they thrive in today’s digital landscape.