每一個 預測分析儀表板建構器 on the first page of Google right now is a product page. Retool will generate one from a prompt. Figma Make will design one. Trickle will drag your spreadsheet into one. They are all real tools and they all work. Not one of them shows you a dashboard that was actually built, actually shipped, and actually made a prediction that could be checked afterwards.
So I built one. Not a demo — a real predictive dashboard over my own infrastructure: 1,321 autonomous agent runs logged between 12 June and 20 September 2026, across 20 job types, running unattended on a VPS. The question it had to answer was the only question that matters in predictive analytics: can I see a failure coming before it lands?
The answer was yes, and then the answer was no, and the gap between those two is the entire lesson. Here is the build, the numbers, the trap I fell into, and the claim my own dashboard proved wrong.
What a Predictive Analytics Dashboard Builder Actually Is in 2026
The phrase has quietly split into two different products, and choosing the wrong one costs you months.
Builder as a design tool. Figma Make, Retool, Trickle, Bold BI. You describe the dashboard, it generates layout, charts and filters, you connect a data source. These are genuinely excellent now. If your data already lives somewhere clean and queryable — a warehouse, a Postgres instance, a tidy sheet — a no-code builder will get you a working dashboard in an afternoon, and you should use one.
Builder as a pipeline. Something has to decide what a row 是, extract it from whatever mess it currently lives in, engineer the features, fit the model, and re-run the whole thing tomorrow when reality has moved. No drag-and-drop tool does this for you, because it is not a design problem.
Here is the part the product pages skip: in most real businesses the second problem is 90% of the work and the first problem is 10%. My data did not live in a warehouse. It lived in 1,321 plain-text log files in a folder, written by 20 different jobs over three months. No schema, no database, no API. That is what most small-business data actually looks like — Stripe exports, inbox archives, form submissions, CSVs a VA has been maintaining since 2023.
A dashboard builder points at structured data. The expensive question is who structures it. In 2026 the honest answer for a solo operator is: an agent does, and it does it in an afternoon. I have written before about what Claude Code agents actually run in my business, and this is the clearest single example of the category.
So the decision is not “which predictive analytics dashboard builder should I buy”. It is “is my data already clean enough for a builder to be the whole answer”. If yes, buy one today. If no, keep reading, because the pipeline is the build.
The Dashboard I Built: 1,321 Agent Runs, One Question
My setup runs a fleet of autonomous brand containers. Each one wakes on a cron schedule, executes one skill — write a blog post, check email, mine social, sweep Search Console — and goes back to sleep. Every run writes a log file. The filename carries the date, the dispatch slot and the job type. The footer carries an exit code and a UTC timestamp.
That is the raw material. Here is what it looked like once structured into rows:
- 1,321 run logs — 12 June 2026 to 20 September 2026
- 20 distinct job types — from
部落客到sendy-sync - 1,306 runs with a parseable exit code (15 logs had none at all — hold that thought)
- 49 hard failures, a non-zero exit — a base rate of 3.75%
A 3.75% base rate is the first genuinely useful number, and it is the one nobody puts on a slide. It means any predictor I build has to beat “assume everything succeeds”, which is already right 96.25% of the time. This is the accuracy trap that kills most predictive dashboards in month two: a model that predicts “no failure” forever scores 96% and is completely worthless.
The per-job breakdown is where the dashboard started earning its keep:
| Job type | Runs | Hard failures | Failure rate | Median minutes |
|---|---|---|---|---|
| social-miner | 103 | 8 | 8.4% | 9.9 |
| 社交海報-2 | 99 | 7 | 7.1% | 8.1 |
| 社交海報-1 | 100 | 6 | 6.0% | 7.4 |
| asana-check | 98 | 5 | 5.1% | 0.9 |
| 部落客 | 99 | 4 | 4.1% | 12.9 |
| 電子郵件檢查器 | 193 | 4 | 2.1% | 2.9 |
| newsletter-writer | 14 | 0 | 0.0% | 5.5 |
| gsc-ga4-sweep | 13 | 0 | 0.0% | 3.0 |
Every job that touches a third-party publishing API sits at the top. Every job that only talks to my own files sits at the bottom. Failure mass tracks external dependency surface, not task complexity — 部落客 is by far the heaviest-reasoning job on the fleet and it fails less often than asana-check, which does almost nothing except call one API.
There is a second distribution hiding in that table. Runtime is wildly non-deterministic. Same job, same prompt, same code: 部落客 has a median of 12.9 minutes, a p90 of 16.7, and a maximum of 53.7 minutes — the slowest legitimate run is 4.2× the median and still produced correct output. Across the fleet the coefficient of variation runs from 0.14 (newsletter-writer, metronomic) to 0.78 (social-miner, chaotic).
That single fact kills the most obvious alerting rule you will ever write. “Alert me if a job runs long” would have paged me dozens of times for runs that finished perfectly. If you are running unattended agents, the runtime envelope is the thing nobody instruments and the first thing that will lie to you.
How to Build a Predictive Analytics Dashboard Builder Pipeline in an Afternoon
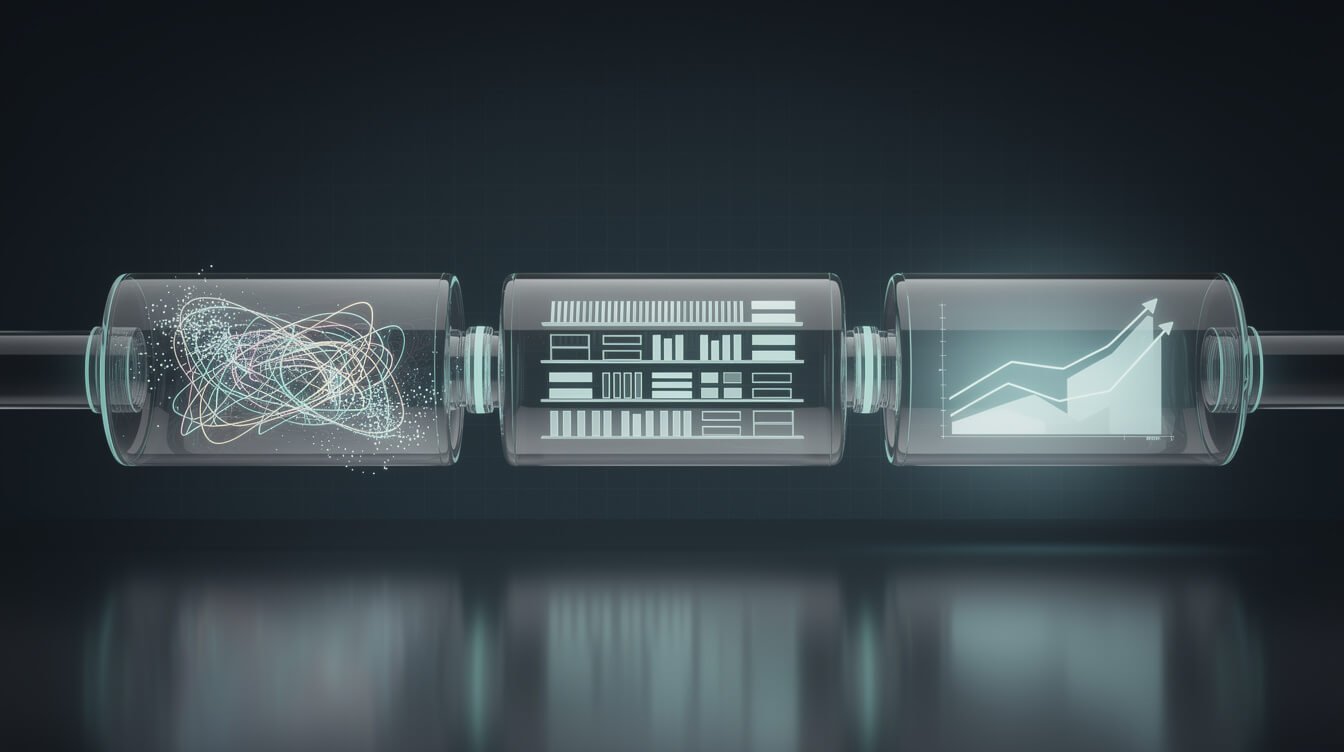
This is the part a no-code builder cannot do for you. Four stages, and only the last one is a dashboard.
1. Define the row before you touch a chart
Every predictive project lives or dies here. A row is one thing that either did or did not do the outcome. For me a row is one run, and the outcome is exit != 0. Write that sentence down before anything else. If you cannot write it in one line, you do not have a predictive problem yet — you have a reporting problem, and a reporting dashboard will serve you better and cost less.
2. Extract with an agent, not a parser you maintain
The extraction is thirty lines of Python: glob the directory, regex the filename for date and job type, regex the footer for exit code and timestamp, derive the duration, count the bytes. I did not write it — I described the log format and the row definition and let the agent write it, then I checked its output against five files by hand.
That checking step is not optional. The agent’s first pass silently dropped every run longer than four hours as a parse artefact, which was correct, and also dropped 15 logs that had no exit code at all, which was 不是 correct — those 15 turned out to be interesting. Read the extraction code. It is the only part of the pipeline where a quiet bug becomes a confident wrong number downstream.
3. Engineer features that exist 前 the outcome
Bold this and tape it to your monitor. A feature is only allowed if it is knowable at prediction time. I will show you in the next section exactly how badly this goes wrong when you skip it.
My candidate features were deliberately dumb: the job type, the dispatch slot, the log’s byte size relative to its own job type’s distribution, and whether the log contained the contract line every skill is supposed to print on completion.
4. Score with lift, never with accuracy
For each feature, split the rows into groups and compute the failure rate inside each group, then divide by the 3.75% base rate. That ratio is lift — how many times more likely a failure is inside this group than at random. Lift is honest in a way accuracy never is at a 3.75% base rate.
No model, no training, no ML library. A grouped count and a division. Ninety percent of small-business predictive analytics is exactly this, and the remaining ten percent should only start once this stops being enough. If you want the infrastructure side of running this unattended, I covered the single box my whole fleet runs on separately.
Steal the whole playbook
I send the actual builds — the scripts, the numbers, and the parts that broke. No theory, no fluff. Grab the AI Playbook and get the next one in your inbox.
The Leakage Trap: My Best Predictor Was Perfect and Completely Useless
Here is the result that made me sit up. Every skill in my system is supposed to end by printing a contract line — SKILL_RESULT: success | .... I tested whether a missing contract line predicts a failed run.
| 團體 | Runs | Failures | Failure rate | Lift |
|---|---|---|---|---|
| Log is missing SKILL_RESULT | 65 | 49 | 75.4% | 20.1× |
| Log contains SKILL_RESULT | 1,241 | 0 | 0.0% | 0.00× |
Combine it with “log size in the bottom decile for its own job type” and it gets absurd: 53 runs flagged, 49 failures inside them, a 92.5% hit rate, 24.6× lift, and it catches 49 of 49 hard failures. One hundred percent recall. Zero false negatives. Perfect separation on 1,306 rows.
A model that separates your outcome perfectly is not a triumph. It is a bug report.
Think about 為什麼 that line is missing. A run that crashes dies before it reaches the line that prints 技能結果. The feature is not predicting the failure. The feature 是 the failure, wearing a different hat. This is target leakage, and it is the single most common reason a predictive dashboard looks brilliant in the build and does nothing in production.
⚡ 取得人工智慧優勢
每週提供真正省時省錢的AI小技巧。沒有廢話,沒有誇大其詞——只有切實有效的方法。.
The test is one question: could I have known this value before the outcome happened? Missing contract line — no. It only exists after the run is already over. It has zero predictive value and I cannot use it to intervene, because by the time I can see it, the thing I wanted to prevent has already happened.
But — and this is why I kept it — a perfect leaky feature is a perfect detector. It is worthless for forecasting and outstanding for monitoring. So it moved out of the prediction column and into an alerting rule, which is where it belongs and where it now earns its keep.
And it immediately paid for itself, because it surfaced the 16 runs I would never have found otherwise.
The 16 ghost runs
65 logs are missing the contract line. 49 of them are hard failures. That leaves 16 runs that exited 0 — reported success — and never printed the line that proves they did the work.
Spread across social-engager (3), 社交海報-1 (3), link-outreach-lead-finder (2), daily-contribution (2), social-miner (2), 部落客 (2), and two others. Sixteen runs that every green dashboard in my stack counted as a win.
That is the real find. Not the 49 failures — those were already loud, already alerted, already fixed. The 16 silent ones were invisible precisely because they exited 0, and exit code is what every monitoring tool on earth watches. This is the exact shape of the agent silent-failure problem: the dangerous failures are never the ones that go red.
The fix is not a better model. It is a property assertion — assert the contract line exists, and treat its absence as a failure regardless of exit code. My detector found a monitoring gap, not a forecast.
Builder Tools vs. Agent-Built: How to Actually Choose
I am not going to pretend the no-code builders are bad. They are very good, and for a large share of readers one of them is the correct answer. Here is the honest split.
| No-code dashboard builder | Agent-built pipeline | |
|---|---|---|
| 最佳時機 | Data is already clean and queryable | Data is files, exports, logs, inboxes |
| Time to first chart | Under an hour | 一個下午 |
| Custom feature engineering | Limited to what the UI exposes | Anything you can describe |
| Cost shape | Per seat, forever | Tokens once, then cents to re-run |
| Who maintains it | The vendor | You — this is the real cost |
| Leakage protection | None. It will happily chart a leaky feature | None either — that is on you |
Note the last row. Neither approach protects you from the mistake that actually breaks predictive dashboards. A tool cannot know which of your columns is downstream of your outcome. That judgement is the job, and it does not come in a pricing tier.
My rule of thumb after this build:
- Data already in a warehouse or a clean table? Buy a builder. Retool or Figma Make will beat anything you hand-roll, today.
- Data in files, logs, exports or an inbox? Agent-built pipeline. The extraction is the project, and a design tool does not do extraction.
- Not sure whether you have a predictive problem at all? Do the grouped-count-and-divide on a spreadsheet first. If no feature clears 2× lift, you do not need a model — you need better data collection.
Most operators asking for a predictive analytics dashboard builder are in bucket three and do not know it. Spending an afternoon proving there is no signal is a genuinely excellent outcome, and it costs you a Saturday instead of a quarter. If you want the wider comparison of where agents fit against no-code, I wrote up the difference between Claude and Claude Code for running a business.
Findings Decay — The Claim My Own Dashboard Falsified
Back in August my own notes recorded a finding I was proud of: all 41 hard failures across the fleet belonged to exactly 2 of the 20 job types, and the other 18 job types had never failed, ever. Clean, quotable, and the kind of thing that ends up in a slide deck.
When I re-ran the analysis for this post over the current 1,321 logs, I got 49 failures spread across 13 of 20 job types, with the top two holding only 30.6% of the total. That is not the same finding. That is the opposite of it.
So I did the thing you are supposed to do and re-ran the query at every historical cut-off to see when it changed:
| As of | Runs | Failures | Job types affected | Top-2 share |
|---|---|---|---|---|
| 15 Aug 2026 | 835 | 39 | 13 of 20 | 33.3% |
| 31 Aug 2026 | 1,053 | 46 | 13 of 20 | 30.4% |
| 10 Sep 2026 | 1,186 | 49 | 13 of 20 | 30.6% |
| 20 Sep 2026 | 1,306 | 49 | 13 of 20 | 30.6% |
It was never 2 of 20. Not in August, not at any cut-off I can construct. The finding was not stale — it was wrong when it was written, and it survived a month because it was quotable and nobody re-ran it.
I am publishing that because it is the most useful thing in this article. A dashboard’s job is not to produce findings. It is to make findings cheap to re-check, so that a wrong one gets caught in September instead of quoted forever. The same decay logic applies to content, which I covered in why content decay is really your claims going out of date.
Practically, that means three things when you build yours:
- Every number gets a re-run date. If you cannot regenerate it in one command, it is a screenshot, not a metric.
- Every finding gets a windowed version. Not “13 of 20 job types” but “13 of 20 as of 20 September, and here is the same query at four earlier cut-offs”.
- Re-run before you quote, always. The re-run cost me one command. The wrong claim cost me a month of confidence.
One more number from the re-run, and this one is good news: the last hard failure on the fleet was 6 September 2026. Every one of the 175 runs since has exited clean. That is a real improvement — and I only know it is real because I can regenerate it on demand.
常見問題解答
What is a predictive analytics dashboard builder?
A tool that turns historical data into a dashboard which forecasts a future outcome rather than only reporting past ones. In 2026 the term covers two different things: no-code design tools that generate the interface from a prompt (Retool, Figma Make, Trickle, Bold BI), and pipelines that extract, structure and model raw data before any chart exists. Most buyers need the second and shop for the first.
Do I need machine learning to build a predictive dashboard?
Usually not. The entire analysis in this article is grouped counts divided by a base rate — no training, no ML library. Start with lift per feature. If nothing clears roughly 2× lift, a model will not rescue you, because there is no signal to find. Only reach for ML once the simple version is genuinely the bottleneck.
What is target leakage and how do I avoid it?
Target leakage is when a feature secretly contains the answer — it is caused by the outcome rather than predicting it. My missing-contract-line feature hit 100% recall because crashed runs die before printing the line. The test is one question: could I have known this value before the outcome occurred? If no, it is leakage. A leaky feature is still useful, just as a detector or an alert, never as a forecast.
Why is accuracy a bad metric for a predictive dashboard?
Because of the base rate. My failures occur at 3.75%, so a model that predicts “never fails” is 96.25% accurate and completely useless. Use lift, precision and recall against the base rate instead. If someone shows you a predictive dashboard and quotes only accuracy, ask what percentage of rows have the outcome — the answer usually ends the conversation.
How much data do I need before this is worth doing?
Enough that your outcome occurs a few dozen times, not enough rows overall. I had 1,306 rows but only 49 failures, and 49 is the number that constrains everything. As a rough floor, aim for 30+ occurrences of the thing you are predicting. Below that you are reading noise, however many total rows you have.
Can an AI agent build and maintain the dashboard on its own?
Build, yes — the extraction and analysis code in this project was agent-written and took an afternoon. Maintain unattended, only with guardrails: my own fleet runs 3.75% hard failures and had 16 runs that reported success while producing nothing. Assert the output contract, not just the exit code, and re-run your findings on a schedule.
最後想說的話
If you came here to pick a 預測分析儀表板建構器, the shortest honest answer is: if your data is already clean, buy Retool or use Figma Make this afternoon and skip the rest. If your data is files and exports and logs — which it almost certainly is — the builder is not the project. The pipeline is the project, and an agent will write it for you in an afternoon.
What that afternoon bought me was not a forecast. It was three things I could not see before: that failure mass tracks external dependencies rather than complexity, that 16 runs had been quietly reporting success while doing nothing, and that a finding I had trusted for a month was never true. None of those came from a model. All three came from structuring the data well enough to ask the question twice.
Build the smallest version. Define the row, extract it, compute lift, and interrogate anything that looks perfect — because on real data, perfect means leakage. Then put a re-run date on every number you publish, including the ones in this article. Mine regenerate in a single command, which is the only reason I trust them.
Get the next build log
Every week I publish what actually ran, what it cost, and what broke — with the numbers attached. Grab the AI Playbook and follow along.
📥 免費:《人工智慧劇本》
我用來經營一人代理公司的所有工具和工作流程。 25 年的行銷經驗濃縮成一份實用指南。免費贈送。.